
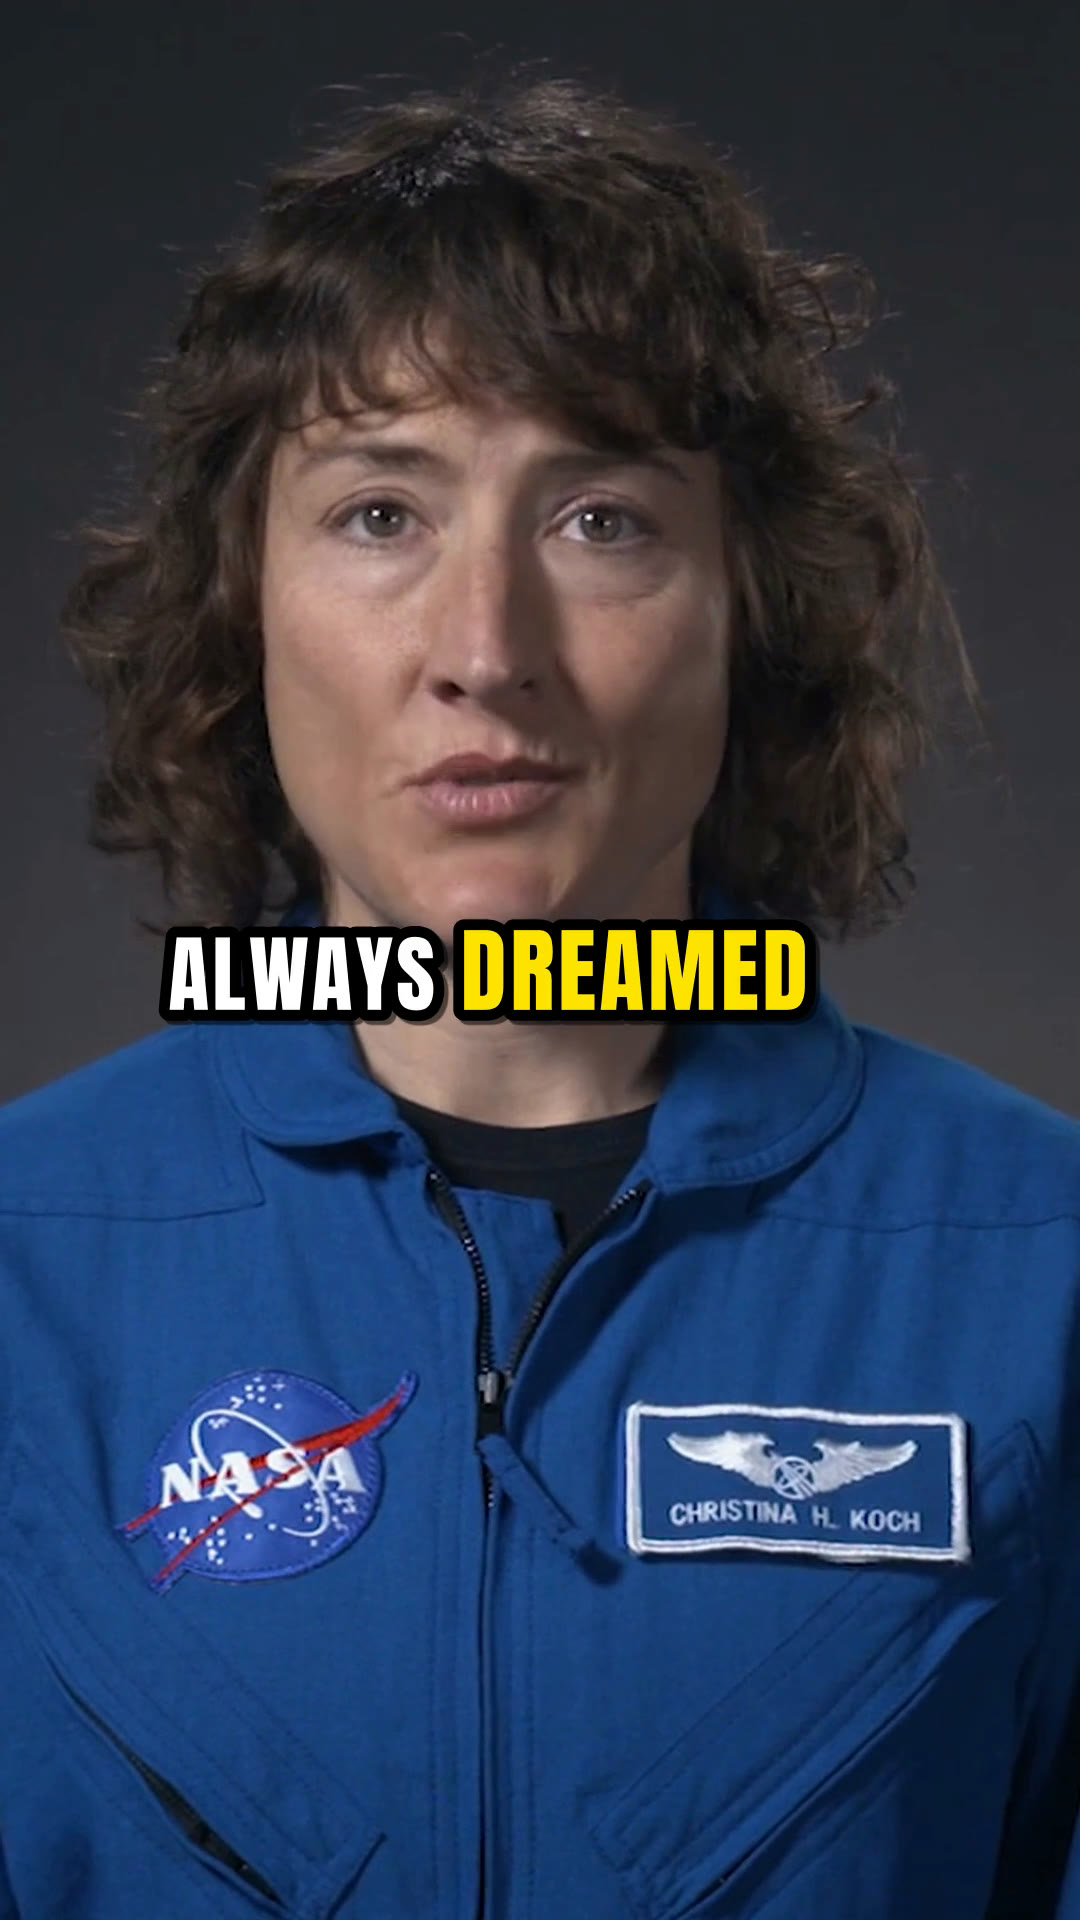
Videos:
final.mp4: 9:16 for Reels · repo copy at 720x1280 (the master is 1080x1920) · 30 fps · 72.3 s · 16.5 MB · -14.0 LUFS · bold-pop captions burned infinal-16x9.mp4: 16:9 · 1920x1080 · 30 fps · 72.3 s · 17.6 MB · -14.0 LUFS · phrase-level clean captions burned in, withfinal-16x9.srtas a sidecar
These are the round-3 versions, after two critic reviews. See Review round below.
The request#
"Cut the ums and long pauses out of this interview clip, add captions, and make a vertical 9:16 version for Reels plus a 16:9 version"
Mode: quick. No questions were asked. The opening line stated the assumptions: keep every sentence in order, remove fillers, shorten pauses over 0.5 s to 0.3 s, use face-tracked 9:16 with bold-pop captions for Reels and 16:9 with clean captions, apply a light grade, master at -14 LUFS, and add no music because the piece is led by speech.
The "user's footage" is an 81 s excerpt of a real public-domain NASA interview. It was found
with showtime assets media search (NASA source, video). It is a sit-down interview with astronaut
Christina Koch, recorded in 2023 for the Artemis II crew announcement, taken from source 1:01-2:22
of NASA/JSC item
jsc2023m000095.
See Sources and license below.
What it demonstrates#
- Editing by transcript. The edit is driven by a word-level transcript (Whisper large-v3-turbo,
262 words). The cut list comes from
edit cut. The hand edits to the EDL were the punch-ins and reframe splits, the grade strength, the caption options, in round 2 a 0.17 s pad before "and readiness" and a 0.22 s tail trim, and in round 3 a fixed crop on one punch-in range. - Fillers and pauses. The filler pass ran and found 0 ums. Parakeet, the engine that keeps disfluencies, confirmed it. NASA's interview was cleanly delivered, so nothing was invented or forced. The pause pass removed the lead-in, the tail and five pauses of 0.6-1.3 s. The clip went from 81.0 s to 72.3 s (-11 %). A Parakeet re-transcription of the final still has all 262 words, so no word was clipped at a cut. Made with showtime 0.1.0. showtime 0.2.0's default transcription (Parakeet v3 plus a filler scan) finds two "uh" in this clip that 0.1.0's tools missed ("more raw uh technical", "great, and uh I hope"); this example was not re-made.
- Hidden jump cuts. Alternate ranges punch in to 1.2x, so each of the 5 real cuts reads as a
change of framing. The last 35 s (one unbroken answer) also changes framing 4 times without a
cut: the range is split into contiguous, frame-aligned source ranges that alternate between 1.0x
and 1.2x, with each join placed in a gap between words. These joins carry no audio fade, so the
room tone runs on unbroken (see Review round). See
project/review/scenes.jpg. - Face-tracked 9:16 reframe. YuNet face tracking with a dead zone keeps her centred without
drift. On one punch-in (0:37.1-0:42.1) the dead zone held the crop on where she started, which
left her at about 60 % of the width, so that range uses a fixed crop on her face instead
(
"fit": "cover", "focus": {"x": 0.503}). - Caption placement is a judgment call, and it was checked in the frames. In the first draft,
bold-pop's default lower third sat exactly on the flight-suit patch and name tag. The captions
moved to
position: middle, on the collar just under the chin, and in round 2 grew to about an 84 px cap height (size0.135,chars16 so the longest line still fits). In round 3 the bold-pop chunks come fromboldpop_captions.py(showtime's own bold-pop pass, plus a rule that no chunk is shorter than 0.20 s). The 16:9 version uses sentence-case phrase captions in the lower 8 %, and every caption change lands on the cut, not 3 frames after it. - Light grade.
teal-orangeat strength 0.3.grade --comparestills showed that--grade autolifted the low-key backdrop and flattened her face, so auto was rejected. - Loudness. Mastered once on the program to -14 LUFS with a -1 dBTP ceiling.
Commands, in order#
showtime is skills/showtime/bin/showtime, run from the working folder. <job> is
showtime-out/nasa-interview-edit-20260926-140703. The helper scripts run with showtime's Python
(PYTHONPATH=skills/showtime/lib ~/.showtime/venv/bin/python).
showtime doctor --quick

# find real footage: a NASA interview with a person on camera
showtime assets media search "astronaut talks about" --type video --source nasa --limit 12 --preview sheet1.jpg
showtime assets media search "astronaut interview"   --type video --source nasa --limit 12 --preview sheet2.jpg
showtime assets media search "NASA Astronaut Candidate" --type video --source nasa --json   # + more queries
#   (durations/sizes checked from each item's images-assets.nasa.gov metadata.json; see friction notes)

showtime job init nasa-interview-edit --platform reels \
  --goal "Cut the ums and long pauses out of this interview clip, add captions, and make a vertical 9:16 version for Reels plus a 16:9 version"
showtime assets media fetch "nasa:jsc2023m000095_Christina_Koch_Artemis_II_Crew_Announcement_Resource_Reel-social" \
  --quality large --max-mb 400 -o raw/
showtime footage probe raw/jsc2023m000095_...-social.mp4                   # 1920x1080, 30 fps, 8:02, stereo AAC
showtime footage scenes raw/jsc2023m000095_...-social.mp4 --every 10 --job <job>   # interview runs 1:01-2:25

# the "user's clip": a one-range EDL (project/raw/excerpt/edl.json), no grade, no loudness
showtime edit render raw/excerpt/edl.json -o raw/koch-interview.mp4

showtime job note <job> --stage understand --verified "..." --assumed "..." --next transcribe
showtime transcribe raw/koch-interview.mp4 --edit-dir <job>/edit --speakers 1 \
  --prompt "Christina Koch, Artemis II, Kennedy Space Center, mission specialist"
showtime pack <job>/edit                                                     # read takes_packed.md
showtime transcribe raw/koch-interview.mp4 --edit-dir <job>/work/parakeet --model parakeet   # filler cross-check: 0

# look choice
showtime footage grade raw/koch-interview.mp4 --analyze
showtime footage grade raw/koch-interview.mp4 --auto --compare --at 20 -o gradetest/auto.png
showtime footage grade raw/koch-interview.mp4 --look teal-orange --strength 0.35 --compare --at 20 -o gradetest/teal.png
showtime footage grade raw/koch-interview.mp4 --look clean-punch --strength 0.4 --compare --at 20 -o gradetest/punch.png
showtime footage grade raw/koch-interview.mp4 --preset subtle --compare --at 20 -o gradetest/subtle.png

# EDL, then draft -> look -> fix (3 passes)
showtime job note <job> --stage plan --verified "..." --assumed "..." --next "edit cut"
showtime edit cut <job>/edit/transcripts/koch-interview.json --max-pause 0.5 \
  --aspect 9:16 --captions bold-pop --grade teal-orange -o <job>/edit/edl.json
#   hand edit: "grade": {"lut": "teal-orange", "strength": 0.3}, "loudness": {"lufs": -14, "tp": -1}
showtime edit check <job>
showtime edit render <job> --preview && showtime edit view <job>             # pass 1: captions on the chest patch
#   hand edit: "zoom" on ranges 2, 4, 6
showtime edit render <job> --preview --overwrite && showtime edit view <job> # pass 2: patch still under captions
#   hand edit: "captions": {"style": "bold-pop", "position": "middle"}
showtime edit render <job> --preview --overwrite                             # pass 3: clean

# round-1 finals, qa and review pack (see "Review round" for what changed)
showtime edit render <job>/edit/edl-16x9.json -o <job>/final-16x9.mp4 --overwrite
showtime edit render <job>/edit/edl.json -o <job>/final.mp4
showtime qa <job> && showtime review-pack <job>

# round 2: apply the critic's findings
#   EDLs: range 3 start 16.37 -> 16.20, range 6 split into 5 contiguous 1.0x/1.2x ranges, tail 77.88 -> 77.66,
#   zoom 1.1 -> 1.2; 9:16 captions {"size": {"portrait": 0.135}, "chars": 16}; 16:9 {"captions": false,
#   "subtitles": "captions-16x9.ass"}
python project/rechunk_captions.py <job>/edit/edl-16x9.json --srt final-16x9.srt \
  --ass <job>/edit/captions-16x9.ass --style clean --position bottom        # 25 phrase cues, shortest 1.12 s
showtime edit check <job>/edit/edl.json
showtime edit render <job>/edit/edl.json -o <job>/final-2.mp4
showtime edit render <job>/edit/edl-16x9.json -o <job>/final-16x9-2.mp4
python project/rechunk_captions.py <job>/edit/edl.json --srt <job>/final-2.srt   # replaces the render's SRT
showtime deliver thumb <job>/final-2.mp4 --at 50 --size 540x960 --fit scale -o round2/after/v_50.jpg   # before/after stills
showtime qa <job>/final-2.mp4 --platform reels                               # WARN: upscale, caption_fast
showtime qa <job>/final-16x9-2.mp4 --platform youtube                        # WARN: caption_fast
showtime transcribe <job>/final-2.mp4 --edit-dir <job>/work/qa-transcript2 --model parakeet   # 262 words
showtime deliver poster <job>/final-2.mp4 --at 25.5
showtime review-pack <job>/final-2.mp4 --platform reels                      # round 2
showtime review-pack <job>/final-16x9-2.mp4 --platform youtube -o <job>/review/16x9
showtime job note <job> --stage feedback --verified "round 2 applied: ..."

# round 3: second critic pass (no blockers)
#   showtime: edit render now skips the 30 ms edge fades between contiguous ranges of one source
#   EDLs: range 6 {"fit": "cover", "focus": {"x": 0.503, "y": 0.25}}; 9:16 {"captions": false,
#   "subtitles": "captions-916.ass"}
python project/boldpop_captions.py <job>/edit/edl.json <job>/edit/captions-916.ass \
  --size 0.135 --chars 16 --position middle                                 # "OUR SKILLS", "THAT THAT"
python project/rechunk_captions.py <job>/edit/edl-16x9.json --srt <job>/final-16x9-3.srt \
  --ass <job>/edit/captions-16x9.ass --style clean --position bottom        # 25 cues, starts on cuts
python project/rechunk_captions.py <job>/edit/edl.json --srt <job>/final-3.srt   # 35 cues
showtime edit render <job>/edit/edl.json -o <job>/final-3.mp4               # 5 of 10 segments re-rendered
showtime edit render <job>/edit/edl-16x9.json -o <job>/final-16x9-3.mp4
showtime deliver thumb <job>/final-3.mp4 --at 39.567 --size 540x960 --fit scale -o round3/after/v_39.567.jpg
showtime qa <job>/final-3.mp4 --platform reels                               # WARN: caption_fast, upscale
showtime qa <job>/final-16x9-3.mp4 --platform youtube                        # WARN: caption_fast
showtime transcribe <job>/final-3.mp4 --edit-dir <job>/work/qa-transcript3 --model parakeet   # 262 words
showtime review-pack <job>/final-3.mp4 --platform reels --force-round        # cut sheet only; no critic

# deliver
showtime deliver exports <job>/final-3.mp4 --targets reels                   # upload master, 48.7 MB
showtime deliver exports <job>/final-16x9-3.mp4 --targets youtube            # upload master, 47.7 MB
python project/export_repo.py <job>/final-3.mp4 final.mp4 reels 720x1280     # 16.5 MB repo copy
python project/export_repo.py <job>/final-16x9-3.mp4 final-16x9.mp4 youtube  # 17.6 MB repo copy
showtime qa final.mp4 --platform reels && showtime qa final-16x9.mp4 --platform youtube   # WARN, WARN
showtime assets credits credtmp --all -o credits.txt   # credtmp/ holds only the source's .license.json
showtime job note <job> --stage deliver --verified "..." --next done
export_repo.py calls st.deliver.exports.export_one with the Reels/YouTube target set to CRF 22
and a 1.85 Mbps video cap (160 kbps audio), keeping showtime's loudnorm, BT.709 tags and faststart.
It is not a raw ffmpeg call. It exists because deliver exports has no size-budget option. The
9:16 repo copy is 720x1280: at this bitrate a 1080x1920 frame smeared skin, and the face-tracked
crop holds only about 608x1080 real pixels anyway. The full-quality masters from deliver exports
(1080x1920 and 1920x1080) are what you would upload.
rechunk_captions.py regroups the same output-timeline words into phrase cues with a small dynamic
program: at most 42 characters per line on 16:9 (32 on 9:16) and 2 lines per cue, breaks preferred
after sentences, clauses and pauses, no line or cue ending on a function word ("the", "of", "to",
"when" ...) or splitting a name when another break fits, and each cue held at least 1.0 s. A cue
that would start up to 250 ms after a cut or reframe starts on it instead. It writes the SRT, and the ASS through showtime's own captions.to_ass in the clean style.
It exists because showtime's grouping split this fast speaker into 80-200 ms one-word cues (see
Review round).
boldpop_captions.py runs showtime's bold-pop grouping unchanged, then merges any chunk shorter
than 0.20 s with a neighbour ("OUR" joins "SKILLS"; "THAT" takes the next "THAT"). It writes the
ASS the 9:16 EDL burns through "subtitles".
Timings#
Measured on a 6-core Intel Mac (x64) whose CPU was shared with about 3 other render jobs.
| Step | Time |
|---|---|
NASA fetch (309 MB, large rendition) |
12 s |
| Excerpt render (81 s clip, one segment) | 159 s |
| Transcribe, Whisper large-v3-turbo (81 s of audio, model load 16 s) | 165 s |
| Transcribe, Parakeet cross-check | 81 s (20-87 s for the 72 s final) |
| Preview renders (720p): pass 1 / 2 / 3 | 169 s / 104 s / 117 s |
| Round 1 finals: 9:16 / 16:9 | 283 s / 328 s (one earlier 245 s 16:9 render was redone, see below) |
| Round 2 finals: 9:16 (10 segments, 2 cached) / 16:9 | 258 s / 161 s |
| Round 3 finals: 9:16 / 16:9 (10 segments, 5 cached each) | 195 s / 104 s |
| Phrase re-chunk (both EDLs) | about 1 s |
deliver exports reels / youtube |
92 s / 116 s (round 3: 65 s / 56 s) |
| Repo-size exports | 34-65 s each |
qa (masters / repo copies) |
22-28 s / 69-75 s |
review-pack |
about 36 s each |
QA summary (round 3)#
- 9:16 master (
<job>/final-3.mp4, 1080x1920, 72.27 s), verdict WARN: 0 fail, 2 warn. File h264 High, yuv420p, 30 fps, faststart, BT.709. Loudness -14.0 LUFS, true peak -1.4 dBTP. No silent gaps, black or frozen stretches.WARN upscale: the source is enlarged 1.78x, or 2.13x on the 1.2x punch-in ranges. That is unavoidable when a 1080p source fills a 1080x1920 frame, and NASA's original is also 1080p. Round 2 raised the punch-in from 1.1x (1.96x) to 1.2x on purpose, so the framing changes read as deliberate.WARN caption_faston the SRT sidecar: phrase cues run over 20 characters/s in her fastest passages (18 of 35 cues). She averages about 19 characters/s across the whole clip, so verbatim phrase captions can't all stay under 20. Round 3 made the 9:16 sidecar favour whole phrases over reading speed, which added cues over 20 (10 of 28 in round 2). The round-1 SRT passed this check only by splitting such passages into 1-2 word flashes, which the rule exempts.
- 16:9 master (
<job>/final-16x9-3.mp4), verdict WARN: 0 fail, 1 warn (caption_fast, same cause, 10 of 25 cues). Enlargement: 1.2x on the punch-in ranges (under qa's 1.5x limit), 1.0x elsewhere. Captions: 25 cues, shortest 1.12 s, none under 1 s (round 1: 85 cues, 8 under 200 ms). - Shipped copies, verdict WARN for both.
final.mp4against reels:resolution(the 720x1280 repo copy, see above) andcaption_fast.final-16x9.mp4against youtube:caption_fast. qa measures both at -14.0 LUFS / -1.5 dBTP. - Words: a Parakeet re-transcription of
final-3.mp4has all 262 words. - Review packs:
<job>/review/round-1/(the first critic's input),<job>/review/round-2/and<job>/review/16x9/round-1/(the second critic's input), and<job>/review/round-3/(built with--force-roundfor the shipped cut sheet; no critic reviewed round 3). - Not checked: listening. Audio was judged from the waveform, the loudness graph, RMS at each join and a re-transcription.
Review round#
Round 1 was self-reviewed and judged "ship". A separate critic then reviewed the round-1 pack plus
the 16:9 and the SRTs. Its verdict was ship after fixes: no blockers, 4 should-fix items and 6
polish items. Each item was checked against the frames or files before anything changed. All of
them were applied in one re-render per aspect. The log is in <job>/work/feedback.md.
| # | Finding (time) | Change |
|---|---|---|
| 1 | 16:9 captions and both SRTs flash 1-2 words: "want" for 80 ms at 0:21.6; 8 and 11 cues under 200 ms | Phrase cues from rechunk_captions.py: 25 on 16:9 and 28 in the 9:16 SRT, each held at least 1.12 s. The 16:9 burns them through the EDL's subtitles |
| 2 | No framing change from 0:36.9 to the end (35 s) | 4 reframe-only changes at 42.07, 48.33, 55.07 and 65.03 s, with no cut and no time removed |
| 3 | The Reels copy reads as current news, but the interview is from 2023 | share.txt Reels line now says "(2023 interview)"; the on-screen tag was optional and was not added |
| 4 | README said the insignia is never a thumbnail element, but the poster shows the patch | Claim reworded (see Sources and license); the poster frame is unchanged |
| 5 | 0.17 s beat before "and readiness" (0:12.3) | Range 3 now starts 0.17 s earlier, which leaves about 0.34 s of silence |
| 6 | 1.1x punch-in reads as a jump cut (0:19.4, 0:36.9) | 1.2x |
| 7 | Bold-pop cap height about 65 px | About 84 px (size 0.135, chars 16) |
| 8 | Repo 9:16 copy soft at 1080x1920 and 1.87 Mbps | Repo copy exported at 720x1280 with the same cap |
| 9 | Last frame has her eyes closed (0:72.3) | Tail trimmed 0.22 s; it now ends on eyes open and a half-smile |
| 10 | README cited a scenes.jpg that isn't in the example |
Shipped as project/review/scenes.jpg |
What the fixes cost:
- The upscale went from 1.96x to 2.13x on the punch-in ranges.
- The honest
caption_fastWARN replaced a PASS that the one-word flashes had earned by exploiting the rule's exemption. - The shipped 9:16 copy now carries a
resolutionWARN. - Two bold-pop chunks ("OUR" at 53.3 s and "THAT" at 61.2 s) lasted 0.15-0.16 s, shorter than round 1's 0.20 s minimum (fixed in round 3).
- Each reframe-only join had a 30 ms audio fade at both edges, which dipped the room tone for about 20 ms (fixed in round 3).
Round 3#
A second critic reviewed the round-2 pack, the 16:9 pack and the SRTs. Its verdict was again
ship after fixes: no blockers, 1 should-fix and 7 polish items. Each was checked against the
files or frames first; all were applied. The before/after stills are in the job's round3/
folder.
| # | Finding (time) | Change |
|---|---|---|
| 1 (should-fix) | README's 16:9 QA line said "No enlargement", but the 16:9 punch-ins are 1.2x | Reworded: 1.2x on the punch-in ranges (under qa's 1.5x limit), 1.0x elsewhere |
| 2 | 16:9 captions change 100 ms after the cuts at 4.43, 26.10 and 37.07 (old text for 3 frames on the new shot) | A cue that would start up to 250 ms after a cut or reframe now starts on it, and the previous cue ends there. At 0:37.1 the new shot now opens on "When I think about the Artemis II crew," |
| 3 | Reframe-only joins at 42.07, 48.33, 55.07 and 65.03 dip the room tone 14-18 dB for about 20 ms | Fixed in showtime: edit render no longer fades the edges between ranges that play one source continuously. Measured in 10 ms windows: the output now stays within 2 dB of the source at each join (round 2: 14-17 dB low) |
| 4 | 9:16 SRT splits phrases ("walls of / my bedroom", "on the / Artemis II", "can be the / way") | Line and cue breaks avoid function words and names. The 9:16 sidecar uses more, shorter cues (35, shortest 1.08 s), e.g. "on the Artemis II / mission to the moon." |
| 5 | 9:16 1.2x range at 0:37.1-0:42.1 is off-centre: face at about 60 %, name tag cut ("KOC") | Fixed crop on her face for that range (both aspects). The name tag now fits the frame |
| 6 | Bold-pop "OUR" (0.16 s) and "THAT" (0.15 s) | "OUR SKILLS" / "REALLY" and "THAT THAT" / "COMPLEMENTS"; every other chunk is unchanged; shortest now 0.20 s |
| 7 | share.txt cover text "ALWAYS DREAMED OF" doesn't match the frame ("ALWAYS DREAMED") |
share.txt now says "ALWAYS DREAMED" |
| 8 | qa of the 16:9 also read the 9:16 SRT | Logged as a showtime issue (qa should read only the video's own sidecar) |
Round 3 was not reviewed again: review.md allows two critic rounds.
What went wrong on the way#
- The first 16:9 final burned captions mid-frame.
edit render --captions cleanreplaces the style but keeps the EDL'sposition: middlefrom the 9:16 plan. The fix was a separateedl-16x9.json, and it cost one 245 s render. - The first two footage candidates were 79-minute satellite "live shots" (3+ GB). Search results show no duration or size, so each candidate's metadata was checked by hand.
- The round-1 self-review missed the caption flashes.
review-packpacks only the latest final, qa's caption check passed them, and the 16:9 was never looked at frame by frame. The critic found them. - The first split of the last range at 47.45 s overlapped the previous range by 10 ms, because each range's end is snapped to whole frames from its own start. The joins were re-set to frame-aligned times before rendering.
Files#
final.mp4,final.srt: the Reels version (720x1280 repo copy) and its phrase-level SRT (optional for Reels; the captions are burned in).final-16x9.mp4,final-16x9.srt: the 16:9 version and its sidecar for YouTube/LinkedIn.poster.jpg: the frame at 0:25.5 ("ALWAYS DREAMED"), 1080x1920.share.txt: Reels and YouTube copy, plus the credit line.credits.txt: the source credit and NASA usage notes.project/edit/edl.json: the 9:16 EDL, andproject/edit/captions-916.ass, the bold-pop file it burns.project/edit/edl-16x9.jsonis the 16:9 EDL, andproject/edit/captions-16x9.assis the caption file it burns.project/edit/transcripts/koch-interview.json: the word-level transcript.project/edit/takes_packed.md: the packed read of the transcript.project/raw/excerpt/edl.json: how the 81 s clip was cut from NASA's reel.project/raw/*.license.json: the license record from the fetch (sha256, URLs).project/rechunk_captions.py: the phrase-level caption chunker.project/boldpop_captions.py: the bold-pop pass with the 0.20 s chunk floor.project/export_repo.py: the repo-size export.project/review/scenes.jpg: the round-3 cut sheet (every scene middle, and each cut at -0.1 s, midpoint and +0.2 s).
The source media is not committed. To rebuild, re-fetch it with the assets media fetch line
above, render the excerpt EDL to project/raw/koch-interview.mp4, run boldpop_captions.py on
edl.json and rechunk_captions.py on edl-16x9.json, then showtime edit render each EDL. The transcript cache is keyed by content, so
the transcribe step re-uses the committed transcript only when the rendered clip is identical;
otherwise re-run transcribe.
Sources and license#
- Footage: "Christina Koch Artemis II Crew Announcement Resource Reel", NASA/JSC, 2023 (NASA
Image and Video Library item
jsc2023m000095_Christina_Koch_Artemis_II_Crew_Announcement_Resource_Reel-social), https://images.nasa.gov/details/jsc2023m000095_Christina_Koch_Artemis_II_Crew_Announcement_Resource_Reel-social. NASA's item description says the reel "includes interview footage and b-roll recorded in 2023". Only the interview portion (1:01-2:22) is used. She speaks about the mission as upcoming, so the post copy says "2023 interview". - License: NASA-produced media, public domain (not subject to US copyright), under NASA's media usage guidelines: https://www.nasa.gov/nasa-brand-center/images-and-media/. No attribution is legally required; it is given anyway.
- No endorsement implied. NASA did not make, review or endorse this edit or showtime. The NASA insignia appears only as the patch on her flight suit in the original footage, so it is visible in every frame, including the poster. The edit adds no NASA logo, title or card. The words are Christina Koch's own: nothing was re-ordered or removed except pauses and silence.
- Fonts: Anton (bold-pop) and Inter (clean), both SIL OFL, bundled by showtime.