
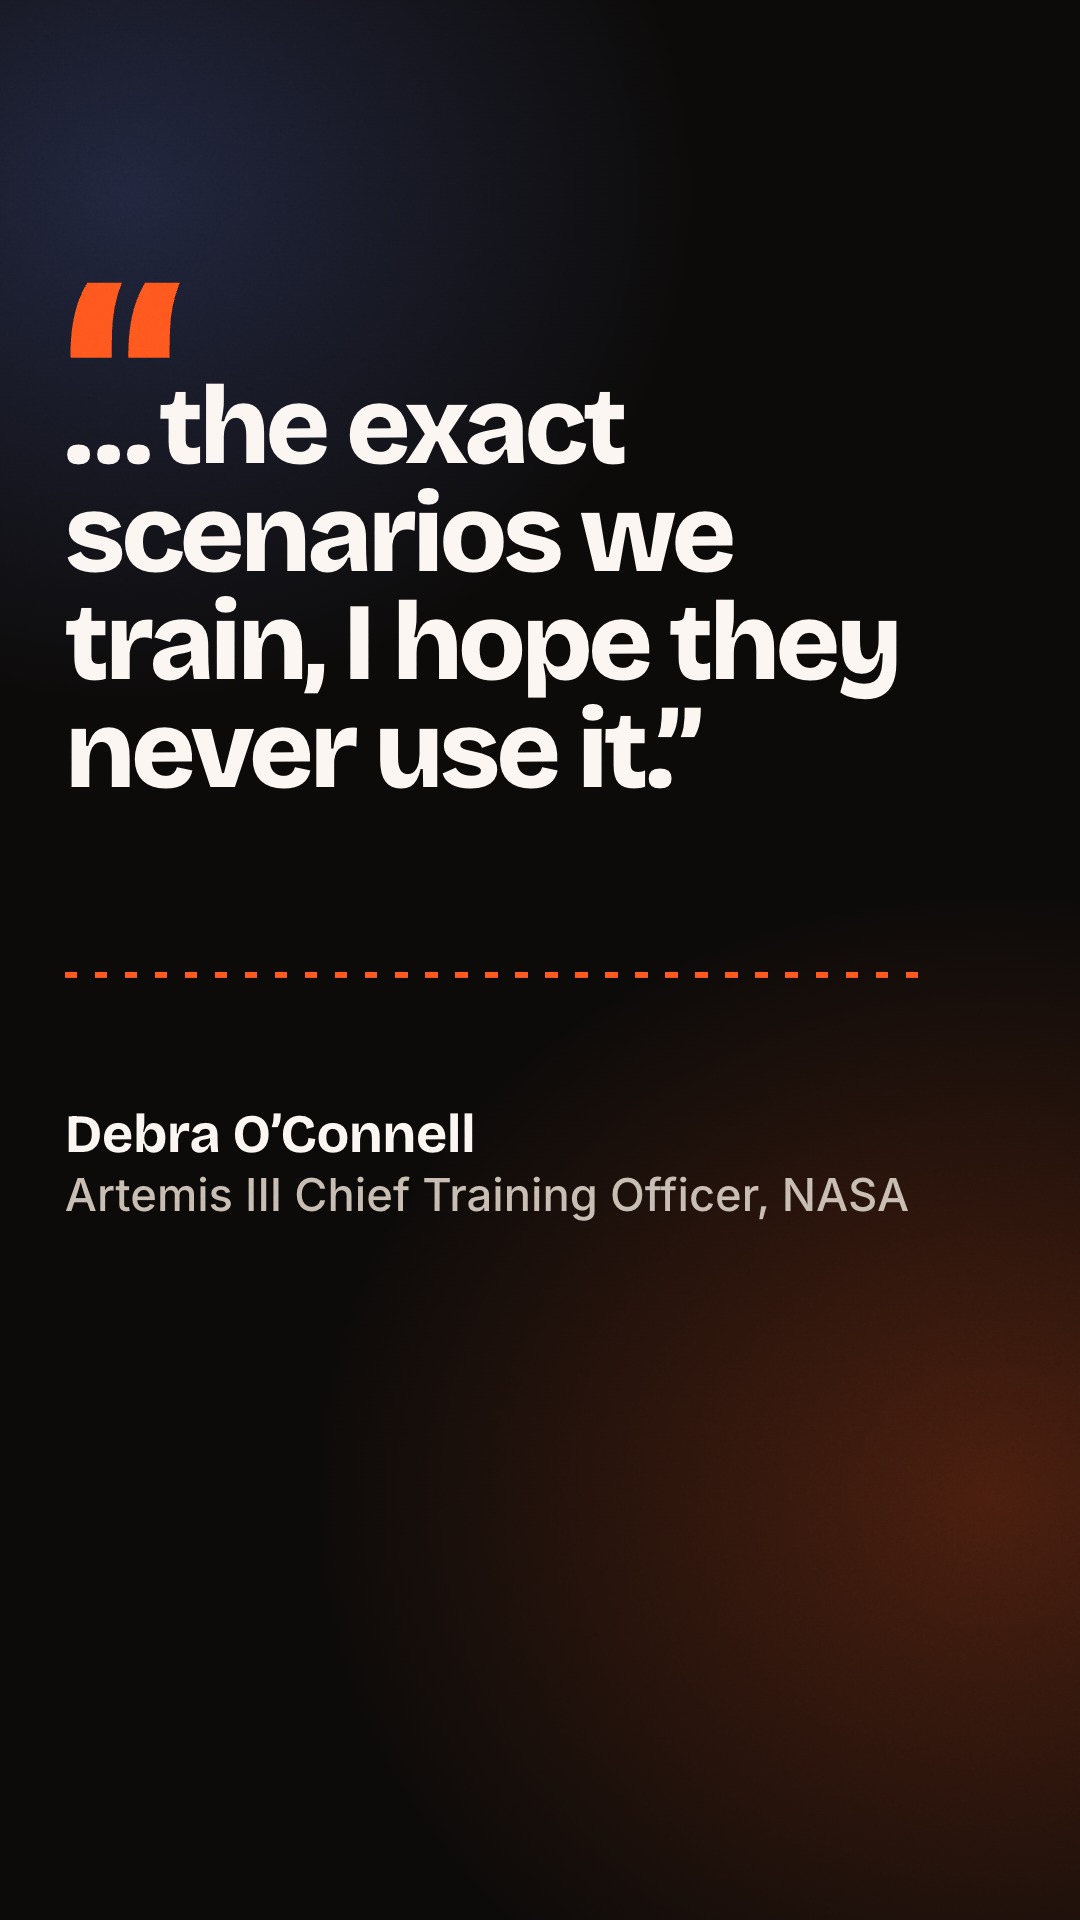
Video: final.mp4 · 1080x1920 · 30 fps · 45.00 s · 19.1 MB · -14.2 LUFS / -1.4 dBTP · loops ·
Captions sidecar (optional, Shorts only): captions.en.srt
The request#
"Cut a 40-second vertical audiogram from this NASA podcast episode for Reels, TikTok and Shorts, with captions and the speakers' names."
The episode: Houston We Have a Podcast, episode 434, "Artemis III Training" (NASA Johnson Space Center, August 21, 2026, 37 min), host Leah Cheshier, guest Debra O'Connell, Artemis III Chief Training Officer.
Mode: quick, publish-bound (license audit and critic pass), with the editor's jobs (range, clean-up) done inline. No questions asked. The opening line stated the assumptions:
Quick mode: one self-contained answer of 35-45 s from the episode, 9:16, the real recording (no synthetic voice), burned karaoke captions from the nasa.gov transcript, name cards with the titles exactly as the episode page gives them,
boldlook, ahip-hop-beatbed at least 20 dB under the speech (dropped if it fights the voice), a loopable end. Exports for Reels, TikTok and Shorts.
Contract: one self-contained answer from NASA's Artemis III Chief Training Officer about what would surprise people about astronaut training, readable with the sound off: most of the training is for failures she hopes the crew never meets.
One correction to the brief, found while reading the transcript: in this episode Artemis III is a test flight whose new, critical phase is rendezvous and docking with the landers, so nothing in the video says "lunar landing". The chosen exchange is about training in general and needs no such claim.
The story#
The range is the host's question and the guest's full answer, episode time 25:09.00-25:45.95, played uncut. The only edit is the cold open: the answer's last sentence (25:42.88-25:45.95) also plays first, under the pull quote, so the payoff arrives before anyone scrolls. The answer then plays through to the same sentence.
| Time | Scene | On screen | Its job |
|---|---|---|---|
| 0-3.4 s | hook |
Pull quote, verbatim, complete at frame 0 (the poster): "…the exact scenarios we train, I hope they never use it." Each word turns ember as she says it; her name and title under the waveform | The payoff line first, in her voice, so scrollers stop |
| 3.4-10.55 s | ask |
The photo band opens (Artemis II crew training in the Orion mockup, labelled); name card "Leah Cheshier · Host, NASA Johnson Space Center"; her question in blue highlight-box captions; the waveform turns blue | Who asks and what: sets up the answer |
| 10.55-29.7 s | answer |
Same photo, still pushing in; name card "Debra O'Connell · Artemis III Chief Training Officer, NASA"; her words in ember bold-pop captions; the host's "That's a good point." and "Yeah." as a small blue pill above | The content: training is mostly worst cases |
| 29.7-40.45 s | team |
Crossfade, on "But by practicing all of those failures", to a close shot of one crew member in the mockup, framed so the face sits between the name card and the photo label; photo, label and waveform fade out together as she finishes (40.3-40.7 s) | The turn of the answer (learning the process, working as a team) gets a new, closer picture |
| 40.45-45.0 s | end |
From 40.85 s, on clean ground: show and episode, "Full episode: nasa.gov/podcasts", "Audio and photos: NASA. Not endorsed by NASA.", a bar filling toward the loop; the text fades out on the hook's ground | Where to hear the rest, the credit, and a clean loop into frame 0 |
Reading it with the sound off: colour is the speaker (blue = host, ember = guest: name card, captions, waveform),
and the waveform is drawn from the voice's own loudness envelope (data/envelope.json, 60 Hz), so it moves only
when someone talks and goes flat in her real one-second pause before answering.
Photos: no photo of this interview or of the Artemis III crew in training was found in NASA's library, so the answer is illustrated with NASA's January 2025 photos of the Artemis II crew in the Orion mockup, labelled "Photos: Artemis II crew training, not the guest (NASA, 2025)" on a dark plate for the whole time they are on screen (the label leaves after the photo has faded out). A photo of another woman at a console (the Artemis II training officer) was rejected because viewers would take her for the guest.
Commands, in order#
showtime is skills/showtime/bin/showtime; <job> is showtime-out/nasa-artemis-audiogram-20260927-141143,
<p> is <job>/project.
showtime doctor --quick
showtime job init nasa-artemis-audiogram --mode quick --platform reels --goal "Cut a 40-second vertical audiogram ..." \
  --assumed "..." --assumed "..." --assumed "..."
# source: the episode page (transcript) and the MP3 it links, both from nasa.gov (see Sources)
curl -sL -o <job>/work/source/episode.html https://www.nasa.gov/podcasts/houston-we-have-a-podcast/artemis-iii-training/
curl -sL -o <job>/work/source/ep434-artemis-iii-training.mp3 https://www.nasa.gov/wp-content/uploads/2026/08/ep434-artemis-iii-training.mp3
showtime footage probe <job>/work/source/ep434-artemis-iii-training.mp3          # 37:18.9, mp3 32 kHz stereo

# range: read the transcript, estimate where the candidates are, transcribe only that window
showtime transcribe <job>/work/source/ep434-artemis-iii-training.mp3 --edit-dir <job>/edit --speakers 2 \
  --from 23:30 --to 29:30 --prompt "Artemis III, Orion, Debbie O'Connell, Leah Cheshier, sim, off nominal"   # 9 m 41 s
showtime pack <job>/edit                            # takes_packed.md -> question 1508.62 s, answer to 1545.81 s
# trim with the mixer (first try from 1508.35 s started on the host's "Um,"; moved to 1509.00 s)
showtime audio mix <job>/work/clip.json -o <job>/work/clip.wav          # {"offset": 1509.0, "dur": 36.95}
showtime audio meter <job>/work/clip.wav                                # -14.0 LUFS, TP -3.3 dBTP
showtime footage denoise <job>/work/clip.wav -o <job>/work/clip.clean.wav --strength 0.5   # DeepFilterNet
showtime audio master <job>/work/clip.clean.wav -o <job>/work/clip.voice.wav --target podcast --preset voice   # -16.0 LUFS
# words: the nasa.gov text aligned to the clip, cross-checked against a fresh transcript of the clip
showtime voice align <job>/work/clip.voice.wav -f <job>/work/align/page_text.txt -o <job>/work/align/clip.page.words.json   # ctc, 106 words
showtime transcribe <job>/work/clip.voice.wav --edit-dir <job>/work --speakers 2 --prompt "Artemis, off nominal"   # 43 s

# photos (public domain, NASA), then portrait crops for the photo band
showtime assets media search "Artemis II crew training Orion mockup" --source nasa -n 12 --min-size 1600 --preview <job>/work/search.jpg
showtime assets media fetch nasa:jsc2025e004086 --quality orig -o <job>/work/photos/jsc2025e004086-orig.jpg
showtime assets media fetch nasa:jsc2025e004075 --quality orig -o <job>/work/photos/jsc2025e004075-orig.jpg

# project
showtime new short <p> --duration 44           # later 45 (end card lengthened for reading time)
~/.showtime/venv/bin/python <p>/tools/build_data.py   # words per speaker, quote timings, speaker turns, envelope
showtime audio mix <p>/audio/mix.json -o <job>/work/mix-test.wav   # composes hip-hop-beat; voice 21.8 dB above the bed
showtime check <p>                              # 7 rounds: contrast, safe zone, text sizes, one determinism error (fixed)
showtime snap <p> --at 0,1.5,3.3,... --width 360 --format jpg --sheet --cols 8     # 8 rounds of stills
showtime render <p> --job <job> --preview       # 720x1280 draft, 53 s
showtime snap <job>/preview.mp4 --every 1.5 --width 240 --sheet --cols 10 -o <job>/work/prev-sheet
showtime audio meter <job>/preview.mp4 --windows 1
showtime render <p> --job <job>                 # final.mp4
showtime qa <job> --platform reels              # FAIL: must_show "Leah Cheshier" not found (see Tool issues) -> fixed
showtime render <p> --job <job>                 # final-2.mp4 -> qa PASS
showtime render <p> --job <job>                 # final-3.mp4 (interjection pill lifted 0.9 % of the height)
showtime qa <job> --platform reels              # PASS, 0 warn
showtime review-pack <job>                      # round 1 -> self-review, then an independent critic pass (below)
# review fixes (see Review round 2)
~/.showtime/venv/bin/python <p>/tools/build_data.py   # "nothing-" -> "nothing—" in the caption words
showtime check <p>                              # PASS, 0 warnings
showtime snap <p> --at 0,9.9,10.1,10.3,10.45,...,44.6 --format jpg --width 540 --sheet
showtime render <p> --job <job>                 # final.mp4 (round 2)
showtime snap <job>/final.mp4 --at 0,7.05,10.475,20.125,25,35.075,40.35,40.49,40.65,42.725 --compare <job>/final-3.mp4
showtime qa <job> --platform reels              # PASS, 0 warn
showtime deliver exports <job>/final.mp4 --targets reels,tiktok,shorts          # round 2 (superseded)
showtime deliver exports <job>/final.mp4 --targets original --max-mb 20

# review round 3: pill below the waveform's full height, brighter "· Ep. 434"
showtime snap <p> --at 17.5,18.1,26.0,26.9 --format png                         # measured pill vs bars vs captions
showtime check <p>                              # PASS, 0 warnings
showtime render <p> --job <job>                 # final-2.mp4 (round 3), 1 min 17 s
showtime qa <job> --platform reels              # PASS, 0 warn, must_show all found

# deliver (round 3 master)
showtime deliver exports <job>/final-2.mp4 --targets reels,tiktok,shorts
showtime deliver exports <job>/final-2.mp4 --targets original --max-mb 20      # this folder's final.mp4
showtime qa <job>/exports/final-2.20mb.mp4 --platform reels                    # PASS, 0 warn
~/.showtime/venv/bin/python <p>/tools/build_data.py                            # + data/words.all.json
showtime captions <p>/data/words.all.json --style bold-pop --size 1080x1920 -o <job>/deliver/captions.ass --srt <job>/deliver/captions.en.srt
showtime assets credits <p> --all -o <job>/work/credits-auto.txt
showtime job discard <job> final.mp4            # (and final-2.mp4)
showtime clean <job> -y                         # freed 96.4 MB
Exports from the round-3 master final-2.mp4 (not committed): reels 25.0 MB, tiktok 25.0 MB, shorts 30.2 MB, all
1080x1920, 45.00 s, -14.2 LUFS / -1.4 dBTP; the master is 65.1 MB (-14.1 LUFS / -1.4 dBTP). This folder's
final.mp4 is the 20 MB-capped original (19.1 MB), which also fits all three platforms.
Features shown#
| Feature | Where |
|---|---|
transcribe --speakers 2 --from --to (a 6-min window of a 37-min episode) + pack |
range picked from takes_packed.md and the nasa.gov transcript |
audio mix as a trimmer (voice track with offset, dur) |
project/source/clip.json |
footage denoise on audio only (WAV in, WAV out) |
clip, DeepFilterNet at strength 0.5 (see the editor's note below) |
audio meter -> audio master --target podcast --preset voice |
clip at -16.0 LUFS before the mix; final master -14 LUFS |
voice align (known text to a real recording, ctc) |
nasa.gov wording on the audio's clock: project/data/clip.page.words.json |
new short (9:16), theme bold |
the project |
caption-karaoke from a real transcript, three layers: highlight-box (host), bold-pop with emphasis and keep ("worst case", "never use it.") (guest), boxed-pill (host interjections, keep) |
project/index.html |
lower-third (card), one per speaker, as clips |
host 3.7-10.3 s, guest 10.45-40.45 s (sequenced, no overlap) |
ken-burns, one continuous push across the ask -> answer cut, a second shot after a crossfade |
photo band |
blur-dissolve, crossfade |
hook -> ask, answer -> team, team -> end |
a data-driven waveform and word highlight (ST.onSeek, pure functions of time) |
#wave, the pull quote |
audio compose hip-hop-beat in mix.json, duck (12 dB, carve 0.4), section_gain on the end card |
project/audio/mix.json |
captions --style bold-pop --srt sidecar |
captions.en.srt (Shorts only; Reels/TikTok get none, per the platform rules) |
assets media search/fetch (NASA, --quality orig), license sidecars, assets credits |
project/media/*.license.json, credits.txt |
check, snap, render --preview, qa --platform reels with expect.must_show, review-pack |
above |
deliver exports --targets reels,tiktok,shorts and --targets original --max-mb 20 |
above |
job note/discard, clean |
ledger, 96.4 MB freed |
assets emoji |
not used: no emoji earned a place in a quote from a NASA training officer |
| crew: editor (range + denoise), researcher (license audit), critic | done inline: this session had no sub-agent tool, so the reviews below are labelled self-reviews |
Editor's note on denoise. The episode is a clean studio recording. DeepFilterNet lowered the room tone in the pauses by 1-2.5 dB and changed the speech bands by 0.1-0.3 dB (measured on the clip), so it runs at strength 0.5: a gentle clean-up that keeps the voice's detail. On a noisy recording this is where full strength goes.
Caption accuracy. The captions are the nasa.gov transcript's words (clean verbatim), aligned to the audio. A fresh transcript of the clip matches 104 of the 106 words exactly; the other two are "worst case" (ASR wrote "worst-case"), and the audio has two "um"s the page leaves out. Start times of matching words differ by 0.08 s (median) between the two methods. Five lines spot-checked against the audio and the page: "What is something that the public might be surprised to learn about from astronaut training for Artemis missions?", "I think the most surprising thing is how little of our training I want them to use in flight.", "That's a good point.", "Nothing off nominal happens during the mission.", "They're working as a team." All match. No ads: the MP3 is the file the nasa.gov page links (not the feed's ad-inserted enclosure), and the chosen range is inside the interview.
Names and titles are the episode page's: "Debra O'Connell" (the transcript's speaker label; the page also calls her Debbie), "Artemis III Chief Training Officer", NASA; the host is introduced on the page as the host of the official podcast of the NASA Johnson Space Center.
The bed. Kept, on the mix report's numbers: the voice sits 21.8 dB above it while anyone speaks (brief: at
least 20), and it carries the 4.5 s end card so the loop never drops to silence. It was not judged by ear in this
session; if it feels off-tone under an interview, delete the bed track from audio/mix.json and re-render.
Review#
Round 1 (on final-3.mp4, self-review from the review pack): ship.
What works: frame 0 is the complete quote with name and title, and her voice says it; the speakers read without sound (colour, name card, caption style, waveform); the end card fades out on the hook's ground, so the loop cut is between two text states on the same background.
Fixed before the pack (seen in drafts):
| # | Finding (time) | Change |
|---|---|---|
| 1 | The host's highlight-box captions hid the next word for 3 frames at each step (4.50-4.57 s): the word switched to dark "active" ink before the box glided under it | White active ink on a darker blue box (#3a55d0, 6.2:1) |
| 2 | The interjection pill touched the guest's next caption (18.1 s, 26.9 s) | Pill lifted 0.9 % of the height; "That's a good point." kept on one card (keep) |
| 3 | Name cards were 26-34 px text in 9:16 and the role wrapped to a lone "NASA" | Name 69 px, role 44 px, balanced wrap |
| 4 | The waveform colour depended on seek order (determinism error at 29.23 s) | Colour is now the current or most recent speaker, computed from t alone |
| 5 | Show kicker and photo label above the safe zone / under 43 px; the pull quote past the right-hand 15 % | Moved and resized; quote re-flowed to four lines |
| 6 | The end card held still 2.8 s | A bar fills toward the loop and the card drifts 2.4 % over 4.5 s |
Polish kept at round 1, with reasons: no caption for ~1 s at 9.6-10.7 s (her real pause before answering). (The name-card overlap and the end card's reading time were kept at round 1 and fixed in round 2, below.) Declined to judge: the bed by ear. Best poster frame: 0.00 s (the pull quote), which is frame 0.
Critic pass on the round-1 pack (an independent read of the same pack): ship after fixes, no blockers. It confirmed the facts, names, captions (word for word against the saved transcript), loudness and licences, and the decision to drop the landing claim.
Review round 2 (fixes on final.mp4, each checked with a still at the cited time against final-3.mp4):
| # | Finding (time) | Change | Verified |
|---|---|---|---|
| 1 | Should-fix: the third dot of the pull quote's "…" touched the "t" of "the" (0 px, 0-3.4 s, also the poster) | The ellipsis is its own box with 0.1 em after it (the quote's -0.04 em tracking closed the gap) | 0 s: 28 px between the last dot and the "t" |
| 2 | Should-fix: in the team shot the astronaut's face sat behind the guest's name card for 10.5 s (29.9-40.45 s) |
The picture starts under the card (top 19.5 % of the height, soft top edge), so the face lands between the card and the label | 35.075 s: face at about y 580-760, card ends at 552 |
| 3 | Should-fix: the photo label left with the name card at 40.45 s while the photo stayed ~0.45 s longer | The photo fades out 40.3-40.65 s; the label stays until 40.7 s, so the photo is never on screen unlabelled | 40.49 s and 40.65 s: label present over the fading photo |
| 4 | Should-fix: the label was white text straight on the photo (2.8-3.2:1 against its brightest background) | Dark plate (#000 at 62 %, rounded), same 43 px text; check contrast PASS |
7.05 s, 35.075 s |
| 5 | Should-fix: the end card's 62-character URL needed ~4.8 s and got 4.0 s | The line is now "nasa.gov/podcasts" (the full URL stays in share.txt); the credit line is "Audio and photos: NASA. Not endorsed by NASA."; check 0 warnings |
42.725 s |
| 6 | Polish: the two name cards overlapped at 10.45-10.53 s ("h Cheshier") | The host's card now leaves at ~10.3 s, before the guest's card wipes in at 10.45 s | 10.1, 10.3, 10.475 s |
| 7 | Polish: the end card faded in over the photo and the orange waveform (40.65 s) | Photo and waveform are gone by 40.65 s; the end text starts at 40.85 s (6 frames later). The text's fade-out no longer holds it visible before it rises (fade-out ... forwards), and the bar starts growing with the text |
40.49, 40.65, 40.8, 41.0 s |
| 8 | Polish: a 3-frame caption gap at 39.97-40.03 s and "USE IT." on screen for only 0.37 s | "never use it." is kept on one card ("THEY / NEVER USE IT.", 39.35-40.74 s), held 0.45 s past the last word | 39.8, 40.0, 40.35, 40.5 s |
| 9 | Polish: uneven word gaps between caption lines (20.12 s) | Spoken emphasis words settle back to their resting size instead of staying 14 % larger, which ate the gaps; only the word being said pops | 20.125 s |
| 10 | Polish: "WORST / CASE SCENARIOS," split across two pages | data-keep="worst case": "TIME TRAINING / WORST CASE" |
20.125 s |
| 11 | Polish: "NOTHING-" ended in the page's hyphen | Shown as "NOTHING—" (em dash), in the burned captions and the SRT sidecar (tools/build_data.py) |
25.0 s |
| 12 | Polish: the role wrapped as "Artemis III Chief / Training Officer, NASA" | Non-breaking spaces: "Artemis III / Chief Training Officer, NASA" | 20.125 s |
| 13 | Polish: a stranger may take the astronaut under the name card for the speaker | The label now says "Photos: Artemis II crew training, not the guest (NASA, 2025)" | 7.05 s |
Kept from the critic's list: the active word still pops 8 % while it is said (by design of bold-pop), so the gap
next to it narrows for a moment. The critic's last note ("whole video") arrived cut off and could not be acted on.
The bed is still unjudged by ear.
Review round 3 (an independent check of the round-2 file: ship; no regressions; the items below fixed):
| # | Finding (time) | Change | Verified |
|---|---|---|---|
| 1 | Should-fix: share.txt alt text described the orange words and the live waveform, which the cover (frame 0) does not show |
Alt text now describes frame 0: the whole quote in white above a dashed orange line | poster.jpg |
| 2 | Polish: the host pills touched the tallest waveform bars (17.5 s, 26.0 s); at full height the bars ran under the pill | Pill data-size 0.78 -> 0.70 and moved down (translateY 4.7 -> 6.2 % of the height): about 12 px below full-height bars and 9 px above the guest's next caption |
17.5, 18.1, 26.0, 26.47 s (bars at full height at 18.1 and 26.47 s) |
| 3 | Polish: the grey "· Ep. 434" in the show line was weak on the bright mockup interior | Near-white at 86 % instead of the muted grey, same shadow | 5.0 s |
| 4 | Polish: this README said the fade-out starts "after her last word" | It starts as she says "use it" (last word ends ~40.59 s): now "as she finishes" |
QA summary#
showtime qa --platform reels on the published file (final.mp4 = the round-3 master capped at 20 MB):
PASS (0 fail, 0 warn, 0 note), -14.0 LUFS / -1.4 dBTP; the round-3 master: PASS, -14.1 LUFS / -1.4 dBTP.
- h264 High, yuv420p, 1080x1920, 30 fps, faststart, BT.709; 45.00 s, as
showtime.jsonexpects - loudness -14.0 LUFS (qa), true peak -1.4 dBTP; no silent gaps, no black or frozen stretches
- frame 0 has the picture (the pull quote,
"poster": 0) and flows into frame 1 - must_show: "Debra O'Connell" (0-40.2 s), "Artemis III Chief Training Officer, NASA", "Leah Cheshier" (4.0-10.0 s), "Not endorsed by NASA" (41.2-44.7 s) all found
- captions drawn by the page (
data-caption), centred at 64 % of the height, inside the 4:5 band and clear of the bottom 25 % and right-hand 15 %; no CC-BY items
showtime check: PASS, 0 warnings (round 3); deterministic; fonts embedded
(Bricolage Grotesque, Inter, JetBrains Mono).
Tool issues found (reported, worked around here)#
check/qadid not see thelower-thirdtext at all over a photo: the component setspointer-events: none, and the text audit's cover test useselementFromPoint, which skips such elements and lands on the opaque scene under them. qa then failedmust_show "Leah Cheshier"and check reported the guest's card as readable for 0.5 s. Worked around withpointer-events: autoon the cards.caption-karaokehighlight-box: the next word switches to the active ink before the box reaches it, so with the theme's dark active ink the word disappears for ~3 frames at every step.lower-thirdin 9:16 sizes incqmin, so the role line is 26 px on a 1080x1920 frame, under check's own 43 px readability floor;position: autoin 9:16 lands at ~69 % height, on top of the caption band.transcribe --speakers 2on the 6-min window labelled every word S0; on the 37 s clip it found the turn into the answer but gave the host's two interjections to the guest. Speakers here come from the nasa.gov labels.footage denoisereturns mono and ~30 ms shorter than its input (36.95 s -> 36.92 s);--strength 0.5and1print the same "noise floor -43.4 -> -44.5 dBFS" line although the outputs differ.review-packlists persistentdata-startlayers (name cards, kicker) as scenes 2-4 ("scene 2 (div)").
Timings#
Shared 6-core Intel i5 with other example builds running.
| Step | Time |
|---|---|
transcribe 6-min window, large-v3-turbo, diarize |
9 min 41 s |
transcribe the 37 s clip |
43 s |
voice align (106 words, ctc) |
7 s |
footage denoise (37 s) |
11 s |
audio mix with the composed bed |
22 s |
check |
28-33 s |
render --preview (720x1280) |
53 s |
render final (1350 frames) |
1 min 17 s |
deliver exports reels + tiktok + shorts |
1 min 33 s |
qa |
12-13 s |
Files#
final.mp4          the video (qa PASS), 19.1 MB
poster.jpg         frame 0: the pull quote (cover image)
captions.en.srt    optional sidecar for Shorts (captions are burned in)
share.txt          Reels/TikTok caption, Shorts title + description, alt text, posting notes
credits.txt        audio, photos, fonts, music
project/           index.html, showtime.json, audio/mix.json, tools/build_data.py, source/clip.json,
                   data/ (aligned words, speaker turns, envelope, the clip's ASR), media/ (two photo crops + license sidecars)
To rebuild: the audio clip is not committed. Download the MP3 (URL below) to project/source/, then from
project/: showtime audio mix source/clip.json -o work/clip.raw.wav,
showtime footage denoise work/clip.raw.wav -o work/clip.clean.wav --strength 0.5,
showtime audio master work/clip.clean.wav -o media/clip.wav --target podcast --preset voice (this reproduced the
original clip.wav bit for bit), then showtime render ..
Sources and licences#
- Audio and transcript: NASA, Houston We Have a Podcast, episode 434 "Artemis III Training" (published
2026-08-21, recorded 2026-08-07), https://www.nasa.gov/podcasts/houston-we-have-a-podcast/artemis-iii-training/;
MP3 https://www.nasa.gov/wp-content/uploads/2026/08/ep434-artemis-iii-training.mp3, both accessed 2026-09-27.
NASA's media guidelines: NASA audio "generally are not subject to copyright in the United States"
(https://www.nasa.gov/nasa-brand-center/images-and-media/). Credited on screen and in
share.txt, with "Not endorsed by NASA". No NASA insignia or show artwork is used (the show art may carry the insignia). - Photos: NASA / Mark Sowa (JSC), jsc2025e004086 and jsc2025e004075, Artemis II crew in the Orion mockup, January 30, 2025, https://images.nasa.gov/details/jsc2025e004086, https://images.nasa.gov/details/jsc2025e004075, public domain (NASA media); cropped. Mission patches on the crew's suits are part of NASA's own photographs, not added graphics.
- Fonts: Bricolage Grotesque, Inter, JetBrains Mono, SIL OFL 1.1, served locally by showtime.
- Music: composed on this machine (
hip-hop-beat, 90 bpm, C minor, seed 1; GeneralUser GS SoundFont). No samples. - Speech clean-up and recognition: DeepFilterNet, Whisper large-v3-turbo and a CTC aligner, all run locally.